mdl <- lm(y ~ x, data = df)
plot(mdl, which = 4)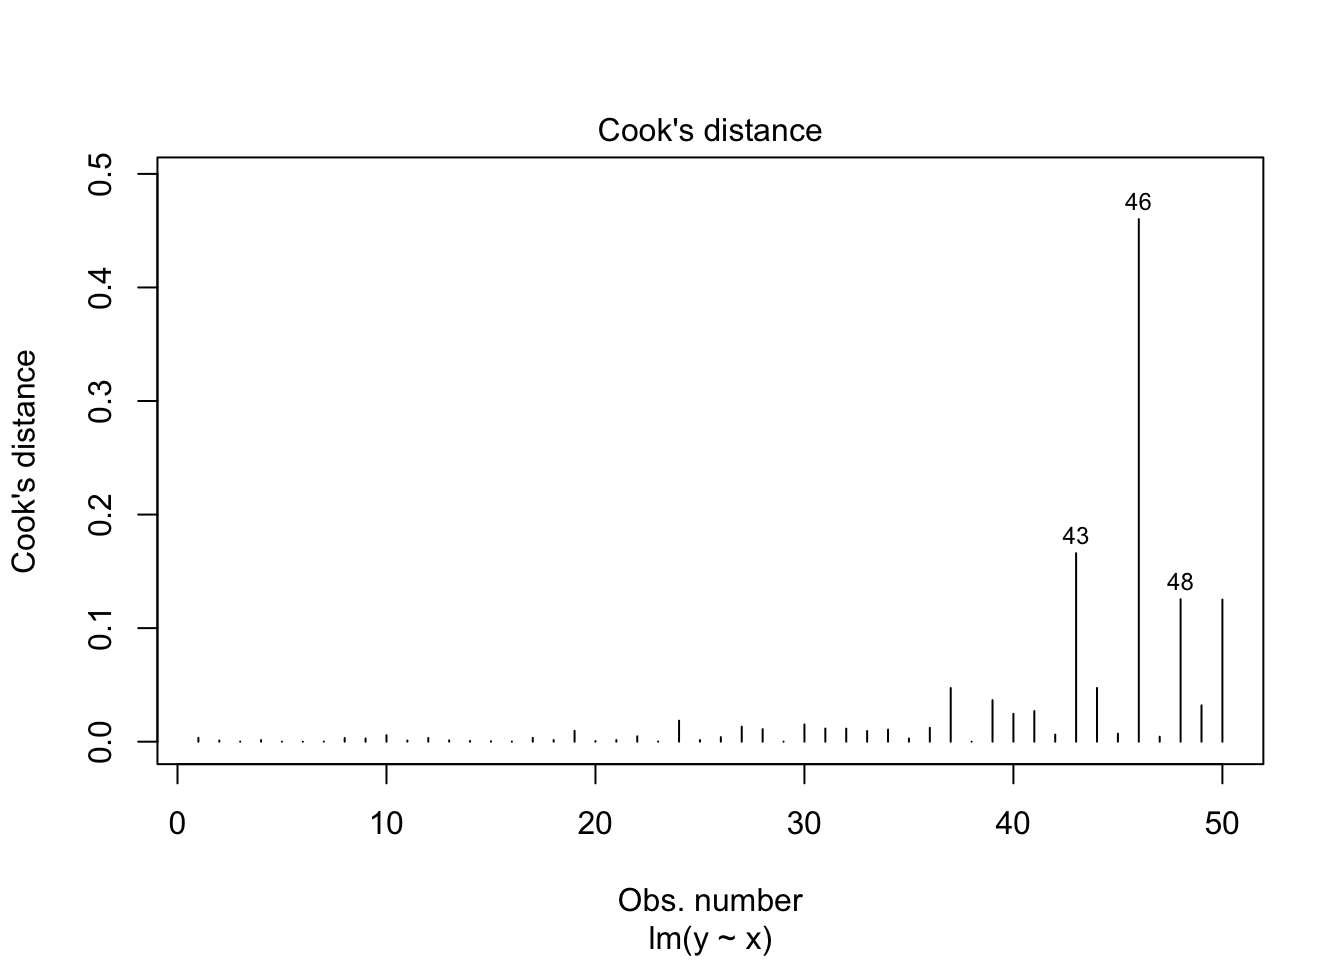
A sensitivity analysis lets us check how sensitive our conclusions are to changes in our modelling approach (here, the removal of observations).
In DAPR2, we’ll do sensitivity analyses by excluding a potentially influential observation, re-fitting our model, and seeing whether the directions (the signs, positive vs. negative) of the coefficients and/or the pattern of statistical significance (and therefore our conclusions based on our model) will change.
Here’s the simulated dataset from the Influential observations flash card, in which the observation in row 46 has a much higher Cook’s Distance than the rest.
mdl <- lm(y ~ x, data = df)
plot(mdl, which = 4)
To do the sensitivity analysis, we must remove observation 46 from the dataset and fit the same model again on that new, smaller dataset. There are two equivalent ways you can do this.
A two-step process: first create a new df with that row removed, then re-fit the model:
# remove the content of row 46
df_no46 <- df[-46,]

# fit a model with the same formula on the new, reduced dataset
mdl_no46 <- lm(y ~ x, data = df_no46)
A one-liner: remove that row within your call to lm():
mdl_no46 <- lm(y ~ x, data = df[-46,])Regardless of how you get the new reduced model, the next step is to compare the coefficients and the pattern of statistical significance in the two models.
Original model, including observation 46:
summary(mdl)
Call:
lm(formula = y ~ x, data = df)

Residuals:
    Min      1Q  Median      3Q     Max
-21.283  -2.289  -0.429   4.356  14.292

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)   1.3455     1.6656    0.81     0.42
x             0.0636     0.0568    1.12     0.27

Residual standard error: 5.8 on 48 degrees of freedom
Multiple R-squared:  0.0254,    Adjusted R-squared:  0.0051
F-statistic: 1.25 on 1 and 48 DF,  p-value: 0.269
Reduced model, not including observation 46:
summary(mdl_no46)
Call:
lm(formula = y ~ x, data = df[-46, ])

Residuals:
    Min      1Q  Median      3Q     Max
-11.150  -2.569  -0.604   4.068  13.059

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)   0.6614     1.4181    0.47    0.643
x             0.1082     0.0491    2.20    0.033 *
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 4.91 on 47 degrees of freedom
Multiple R-squared:  0.0935,    Adjusted R-squared:  0.0742
F-statistic: 4.85 on 1 and 47 DF,  p-value: 0.0326
This is a rare and fun outcome!
A predictor that was not significant in the original model has now become significant in the reduced model. (More often the change goes in the opposite direction: a significant result becomes non-significant.)
If there were no difference between the conclusions you’d draw from the two models, you’d report that:
Since there is a difference between the conclusions you’d draw from the two models, you’d report that:
x changed from 0.06 to 0.11 and became significantly different from 0 (p = .033).The decision of which model to use to draw conclusions from is not always clear-cut. You must use your researcher judgement and ask yourself: do you believe that that influential data point is a legitimate sample from the population you’re interested in studying?
If something about that observation tells you that it doesn’t seem to come from your population of interest, then you are justified in removing it and focusing your interpretation on the updated model.
If you believe that it does still come from your population of interest, then the discussion becomes more interesting: you can talk about both models and speculate about why you think that particular observation has such an impact. In this case, we recommend a cautious and conservative interpretation, since your conclusions have still changed from one model to another, so you should be much more tentative in any conclusions you draw.