library(car)
vif(INSERT_MODEL_NAME)Checking multicollinearity
When predictors are correlated, we call this “multicollinearity”. It’s often the case that predictors are a little bit correlated. But what we don’t want is predictors to be highly correlated. When predictors are highly correlated, the model doesn’t know what information comes from which predictor, so the variance of its estimates increases (that is, the precision becomes worse).
When is multicollinearity a problem? When is it not?
Multicollinearity is a problem when the key predictor(s) of interest—the ones that will help us address our RQ—are highly collinear with other predictors in the model.
Why is this a problem? Because the standard error of our key predictor(s) will be larger, which means a less precise estimate, which means that our p-value for that predictor will be bigger, which means that we’re more likely to make a Type II error (failing to reject the null hypothesis when we actually should be rejecting it).
Multicollinearity is not a problem when the only predictors that are highly collinear are covariates or control variables. In those cases, it only matters that they’re in the model at all—our goal is to control for them, not interpret them.
Measuring multicollinearity using VIF
We assess multicollinearity using the variance inflation factor (VIF).
The vif() function from the car package will provide VIF values (or for categorical predictors, GVIF) for each predictor in your model.
CautionMathematical formula for multicollinearity
For a given predictor \(x_j\), VIF is calculated as:
\[ VIF_j = \frac{1}{1-R_j^2} \\ \]
Interpreting VIF values
Suggested cut-offs for VIF are varied. Some suggest 10, others 5. We’ll combine those thresholds and say:
- Close to 1 is ideal.
- Below 5 is low, no need to worry.
- Between 5 and 10 is moderate, start to worry here.
- More than 10 is severe, cause for lots of concern.
What do we do if we have high VIF?
Actually dealing with correlated predictors is beyond the scope of DAPR2.
CautionBut I want to know anyway
In DAPR3, you’ll learn how to combine multiple variables into a “composite measure”: a single variable that’s a compressed version of the original variables and contains much of the same information that they contained.
You can make a composite measure out of the correlated predictors, and then use that composite measure to replace the original collinear predictors in the linear model.
For now, we just want you to know what effect multicollinearity has on model estimates and to be able to identify it.
One thing you should not do if you have high VIF is delete correlated predictors just because they’re correlated. Your predictors are in your model for a reason—because your RQ wants them there, or because they’re important covariates or control variables. So it’s important that they stay.
Examples
High VIF
We have a data set called corr_df with an outcome variable y and two predictors x1 and x2.
corr_df |> head()# A tibble: 6 x 3
y x1 x2
<dbl> <dbl> <dbl>
1 -1.65 -1.29 -0.973
2 0.305 0.655 0.869
3 1.62 1.96 1.33
4 -1.55 -1.94 -1.10
5 -0.384 -1.27 -1.69
6 -0.797 -0.659 -0.812Here’s a plot that shows the correlation between x1 and x2.
corr_df |>
  ggplot(aes(x = x1, y =  x2)) +
  geom_point()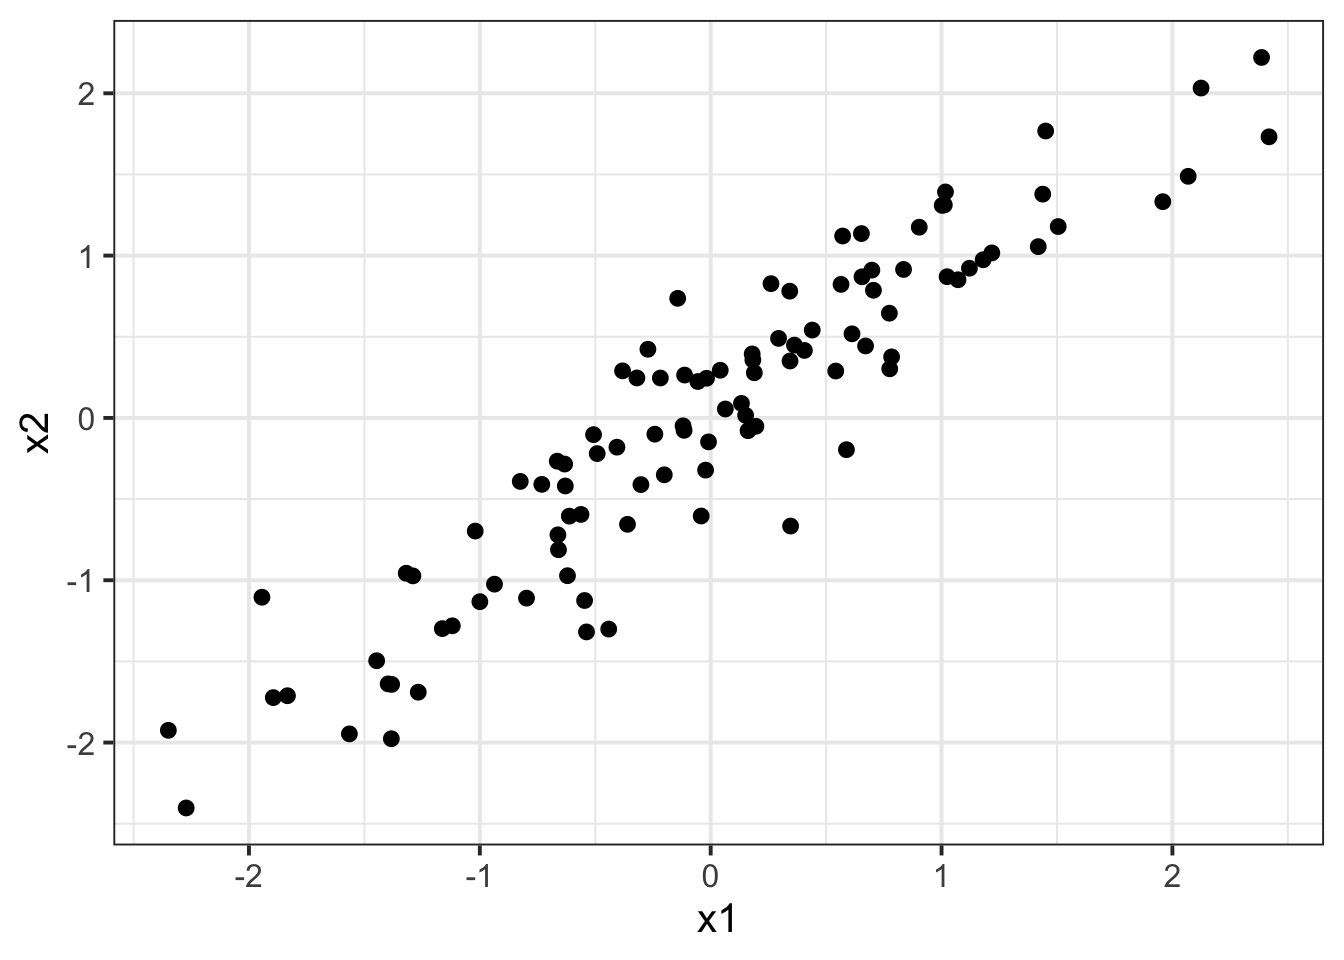
In corr_df, x1 and x2 are highly correlated. The correlation appears as a strong diagonal line.
Let’s fit a model and check its VIF:
m_corr <- lm(y ~ x1 + x2, data = corr_df)
car::vif(m_corr)
x1 x2
7.4 7.4 Because this value is above 5, the variance of each predictor is much bigger than it would be without the other predictor in the model.
Low VIF
Here we have a data set called uncorr_df, again with an outcome variable y and two predictors x1 and x2.
uncorr_df |> head()# A tibble: 6 x 3
y x1 x2
<dbl> <dbl> <dbl>
1 -1.40 -0.604 -1.53
2 0.667 0.875 -0.0539
3 1.78 1.21 1.35
4 -1.67 -1.05 -1.38
5 -1.22 -1.80 0.353
6 -0.814 -0.596 -0.561 Here’s a plot that shows the correlation between x1 and x2.
uncorr_df |>
  ggplot(aes(x = x1, y =  x2)) +
  geom_point()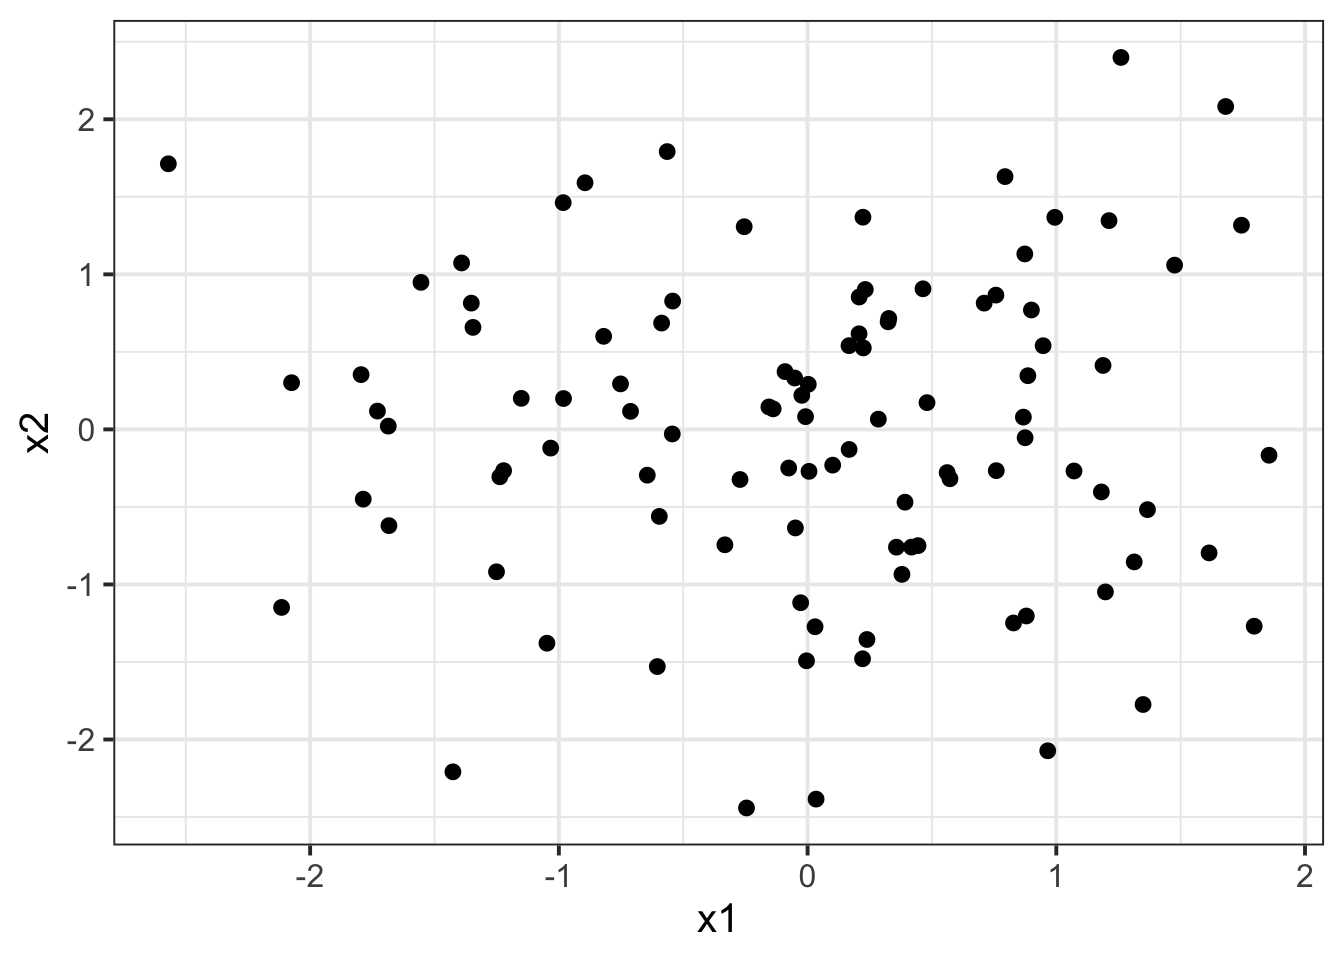
In uncorr_df, x1 and x2 are not very correlated. The lack of correlation appears as the big dispersed cloud of data points.
Let’s fit a model and check its VIF:
m_uncorr <- lm(y ~ x1 + x2, data = uncorr_df)
car::vif(m_uncorr)
x1 x2
1 1 Hurray, VIFs equal to 1! This is the ideal scenario: removing one of the predictors doesn’t change the variance of the other predictor at all.
For Block 3: Multicollinearity in interaction models
Interaction terms often result in multicollinearity, because interaction terms are the product of the original predictors. So of course they’re correlated: they’re mathematically very closely related!
Here’s a trick: if you have problematic multicollinearity for your interaction term, then try mean-centering the interacting predictors. Often this will help reduce the VIF/GVIF.