df |>
  ggplot(aes(x = x, y = y)) +
  geom_point()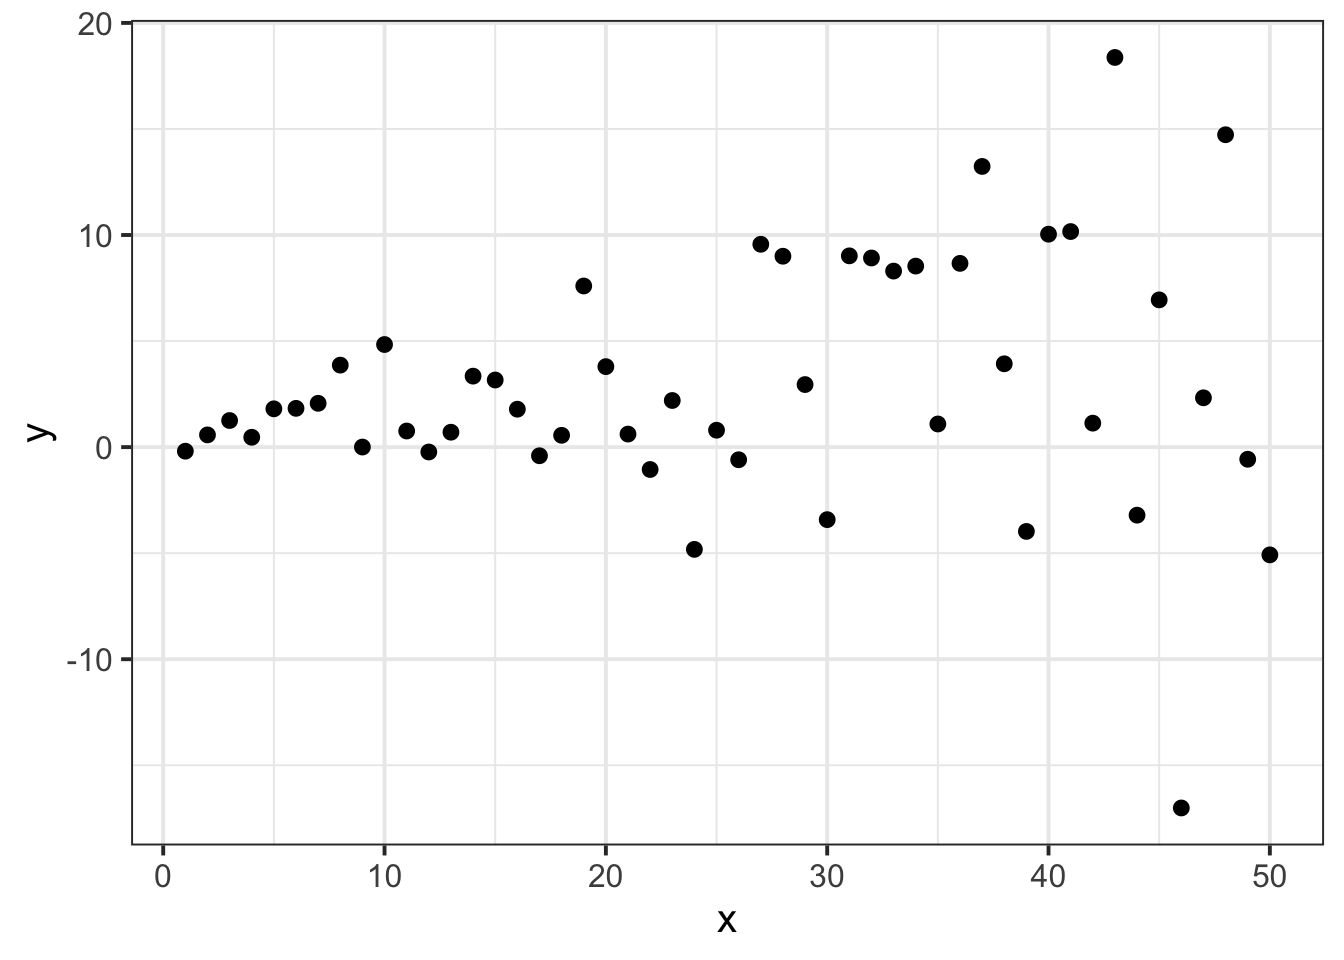
Sometimes, individual observations that don’t behave like the rest of the data can influence the estimates of the regression model.
To check the influence of each data point, we use a measure called Cook’s Distance. Cook’s Distance refers to the average distance the predicted outcome values will move if a given case is removed.
In R, the cooks.distance(modelname) function will provide these values. You can plot them with plot(modelname, which = 4).
Here’s a simulated dataset (with very unequal variance!) where we’ll model how continuous x is associated with continuous y.
df |>
ggplot(aes(x = x, y = y)) +
geom_point()
Fit a model:
mdl <- lm(y ~ x, data = df)Now, we can find the Cook’s Distance of each observation. This function will print out a value for each observation in the dataset. It represents how much the model’s estimates will change if that particular observation were removed.
cooks.distance(mdl) |> head() 1 2 3 4 5 6
3.48e-03 1.02e-03 9.37e-05 1.41e-03 2.04e-05 9.61e-06 It’s easier (for me at least!) to interpret these values in a plot:
plot(mdl, which = 4)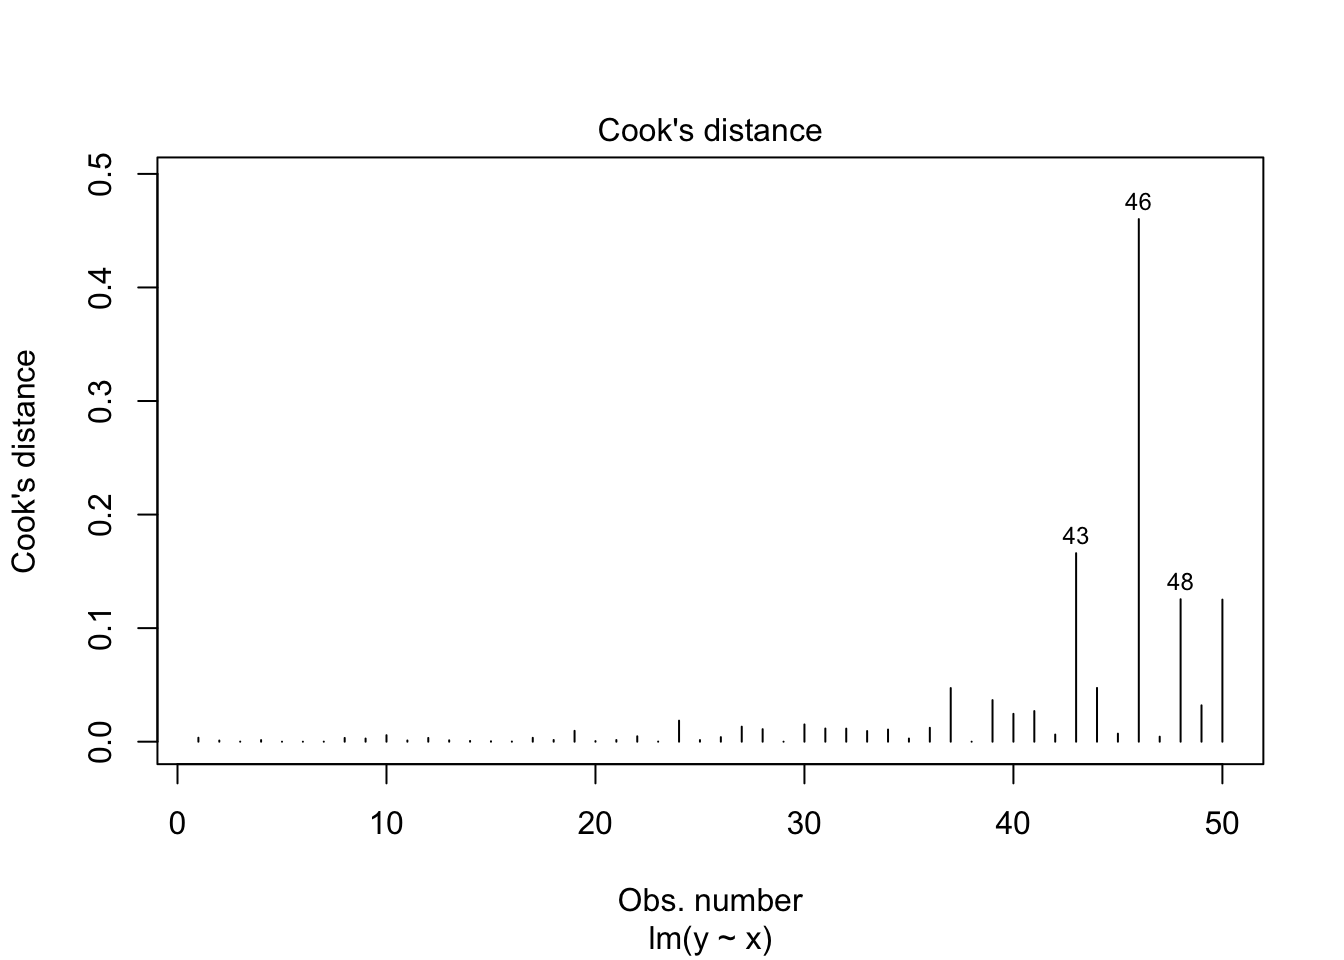
Looks like observation 46 is pretty darn influential, compared to all the rest!
In the plot above, it looks like the Cook’s distance of observation 46 is at least two times larger than the next-largest Cook’s distance, that of observation 43.
Our rule of thumb is to eyeball the plot to check if you have a single observation with a Cook’s distance that appears more than two times larger than the next-biggest Cook’s distance. If you do (like we do above), then that’s an observation worth investigating.
The first step is to re-examine your data. Could it be the case that you have missed some impossible values (e.g., a negative value of a person’s height), values outwith the possible range (e.g., a score of 55 on a survey where scores can only range 10-50), values that don’t make any sense (e.g., an age of 200), or maybe there are even typos / data entry errors (e.g., forgetting to put a decimal point, so having a height of 152m instead of 1.52m)?
If after re-examining your data you cannot identify any atypical, non-normal, or impossible values, you should conduct a sensitivity analysis to see how much this influential value may be impacting your conclusions.
In R, we can get lots of these measures with the influence.measures() function:
influence.measures(my_model) will give you out a dataframe of the various measures.summary(influence.measures(my_model)) will provide a nice summary of what R deems to be the influential points.Belsley, D. A., Kuh, E., & Welsch, R. E. (2005). Regression diagnostics: Identifying influential data and sources of collinearity. John Wiley & Sons. DOI: 10.1002/0471725153↩︎